01 / The problem
Teach agents to cooperate at the card table
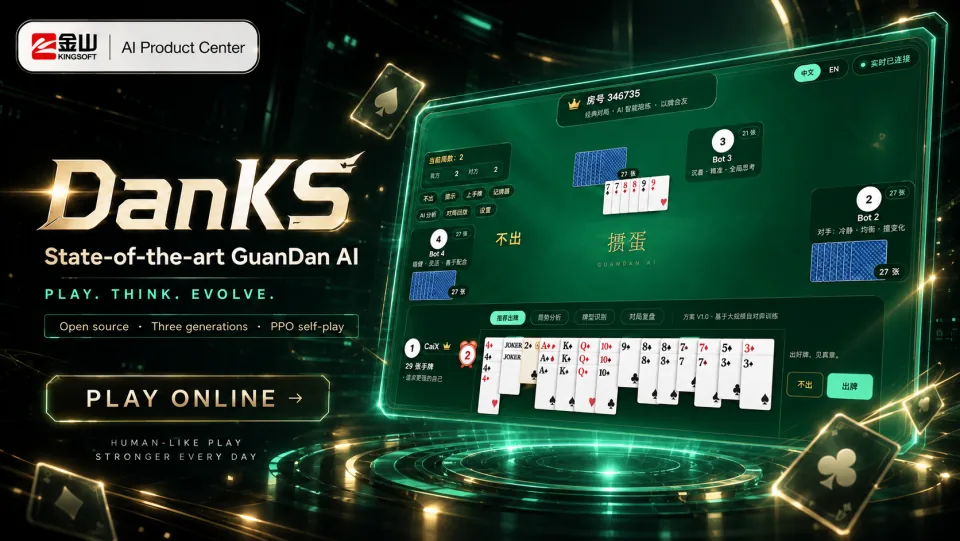
Four-player Guandan involves hidden hands, combinatorial actions and long-term partnership. The project explores card-playing decisions through legal actions, candidate retrieval and policy learning.
02 / Approach
Reinforcement learning · Game AI
Approach
From structured candidate retrieval to learned action selection and memory-based PPO policies, DanKS shares three generations of implementation that connect a rules engine, policy models and self-play training.
Initiated by Kingsoft's AI Product Center, with Zhenxin Lin contributing to research and development.
03 / Explore the code
Explore the implementation
Complete rules engine
A shared rules engine for 108-card Guandan, including legal-action generation and game-state handling.
Three generations of strategy
Compare V1 structured retrieval, V2 learned selection and V3 memory-based policies.
Self-play training
PPO training combines state and candidate-action features through policy and value models.
Start with the documentation